Transport analytics / Case study
Turning Movement Count Estimation
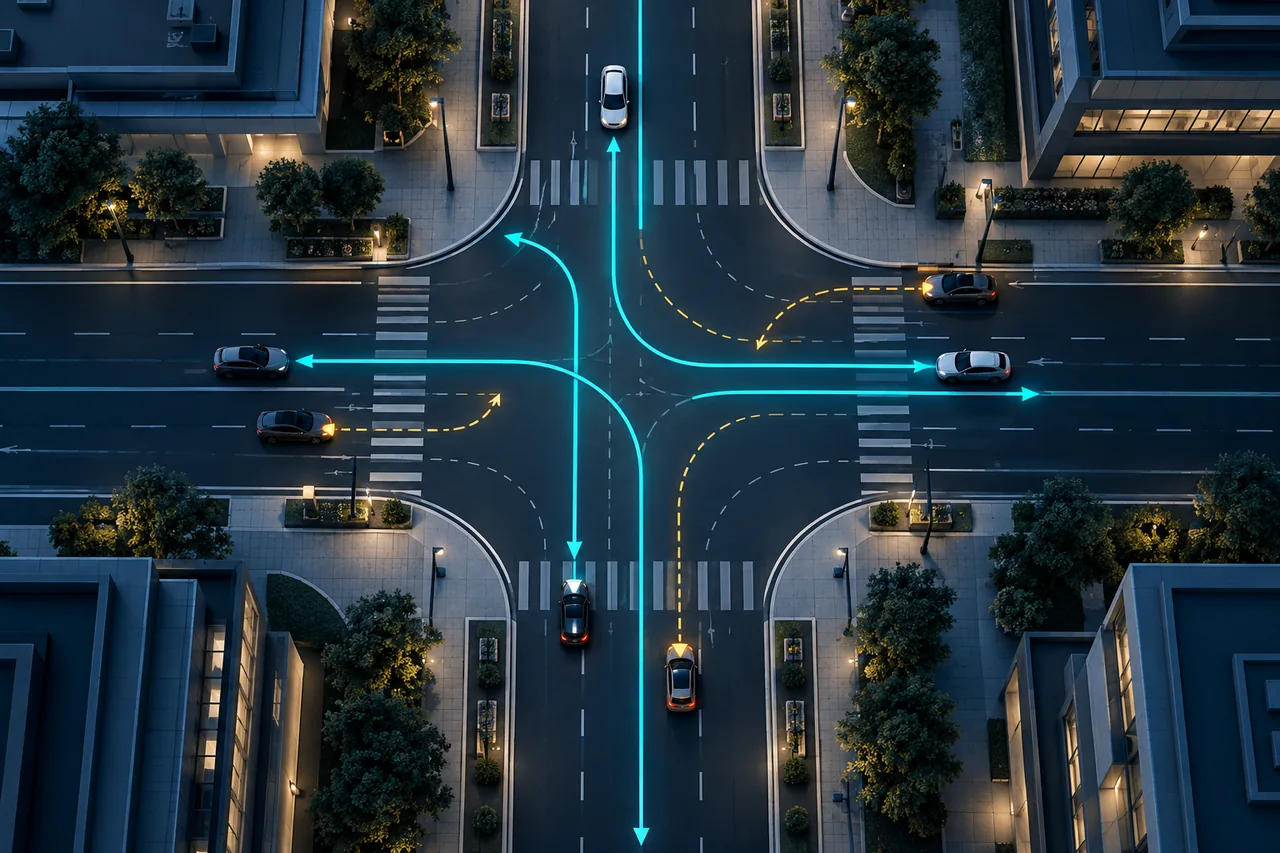
I developed a traffic-estimation workflow that combined large-scale data preparation, seasonality analysis and tree-based models to estimate vehicle turning movements.
 Harshit Makwana
- My role
- Data engineering, traffic modelling & visualization
- Timeline
- 2022–2023
- Focus
- Transport analytics
01 / Context
Connecting road data, changing traffic patterns and retrainable models.
Turning-movement estimates need to account for more than a single traffic snapshot. My work examined changes associated with weekdays, festivals and the COVID-19 period, while addressing anomalies and inconsistencies in data collected from different sources.
02 / Ownership
What I built
- Gathered millions of data points through web scraping, APIs, downloads and paid data services.
- Analysed seasonality and anomalies, including weekday patterns, festivals and COVID-19-related changes.
- Used the GEH formula in the outlier-screening workflow and developed preprocessing scripts in PostgreSQL, Trino and PL/SQL.
- Mapped and connected road records in Python, trained and compared models, and visualized results for clients.
- Developed a retraining pipeline so new data and changing traffic trends could be incorporated into the modelling workflow.
03 / Engineering
Technical approach
Prepare connected road-level data
I combined data acquisition with database-side preprocessing and Python mapping. This work brought road records and their associated values together before modelling, while seasonality analysis informed how I interpreted unusual observations.
Compare models and support retraining
I evaluated Random Forest and XGBoost and also experimented with CatBoost and LightGBM. I built the surrounding pipeline to make retraining easier as new observations and traffic trends became available, then presented the resulting data through client-facing visualizations.
04 / System view
Workflow at a glance
Traffic sources
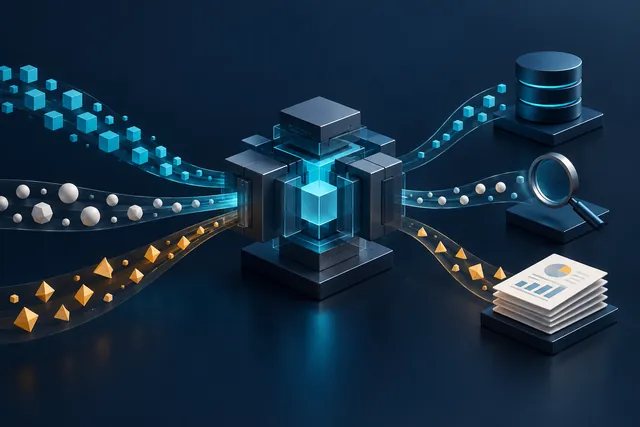
APIs, scraping and downloaded datasets
Preparation
GEH screening, SQL processing and road mapping
Model evaluation
Tree-based model experiments
Delivery
Client visualizations and retraining pipeline
05 / Delivery
Outcomes
- Random Forest — reported accuracy
- 86%
- XGBoost — reported accuracy
- 94%
The project recorded an accuracy score of 86% for Random Forest and 94% for XGBoost. Alongside those results, I delivered preprocessing, mapping, visualization and retraining workflows.
These are the accuracy figures recorded for the project. The metric definition and validation split are not published here, so they should not be read as a standardized benchmark.
Technologies & methods
- Python
- PostgreSQL
- Trino
- PL/SQL
- Random Forest
- XGBoost
- CatBoost
- LightGBM